
Adaptive Visual Grounding for Robot Vision
A deployed robot-vision system that converts natural-language instructions into localized visual targets across still images, recorded video and browser-camera inputs.
- YOLO
- OWL-ViT
- GPT
- Visual Grounding
01
What it does
A deployed robot-vision system that converts natural-language instructions into localized visual targets across still images, recorded video and browser-camera inputs.
The system parses objects, attributes, quantities and spatial relationships, then routes requests across YOLO, OWL-ViT and GPT-guided OWL-ViT while producing structured bounding boxes, confidence, timing information and annotated outputs.
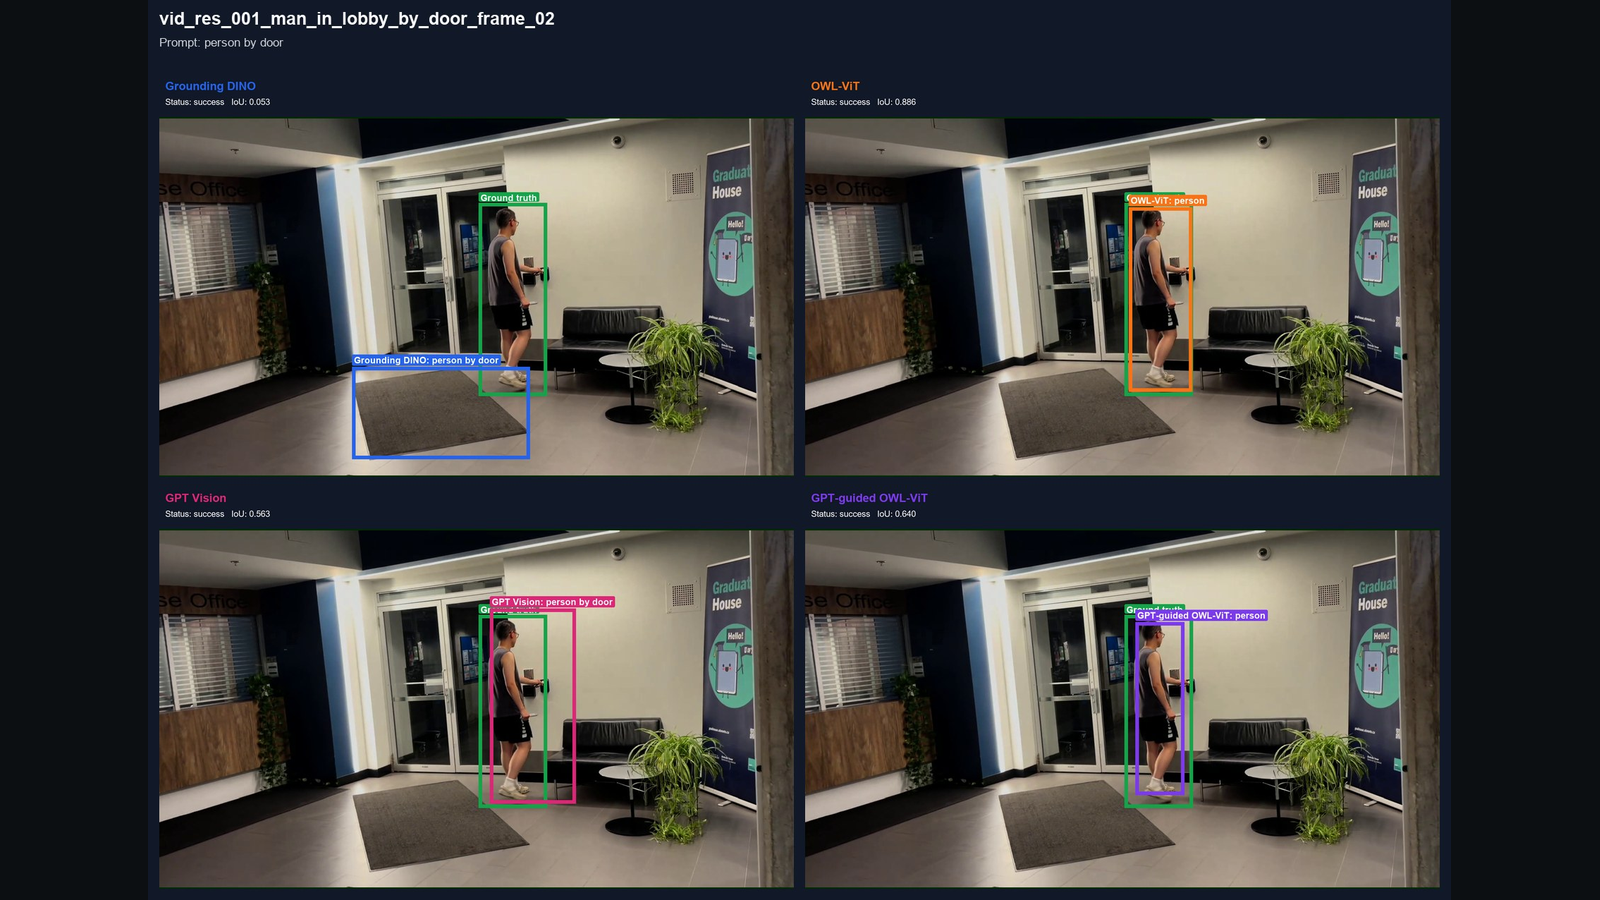
To determine which approach worked best, I compared Grounding DINO, OWL-ViT, GPT Vision and a custom configuration on the same 105-image evaluation set. Based on those results, I designed and implemented a custom GPT Vision-guided OWL-ViT pipeline to improve grounding accuracy. The pipeline combines OWL-ViT open-vocabulary proposals with GPT Vision-based instruction interpretation and candidate selection, followed by local refinement, bounded box checks and tracking/re-acquisition for video and live-camera use.
02
Demonstrations
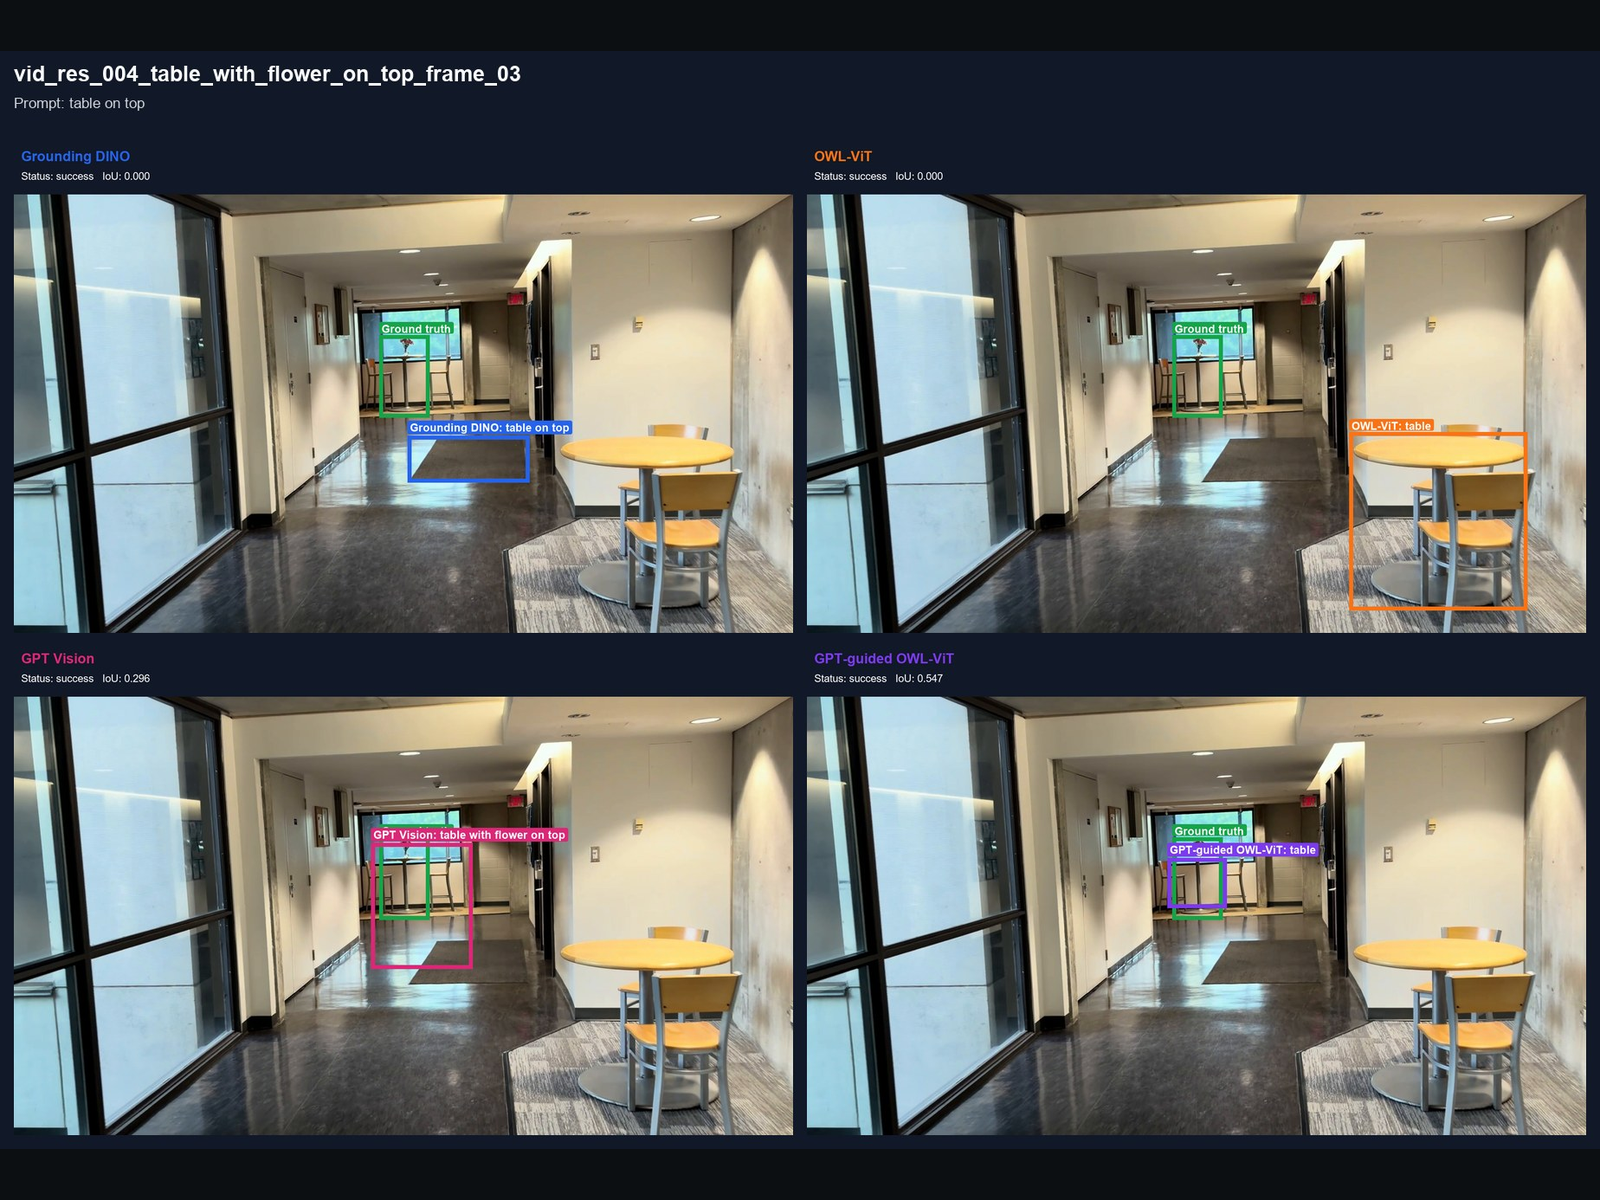
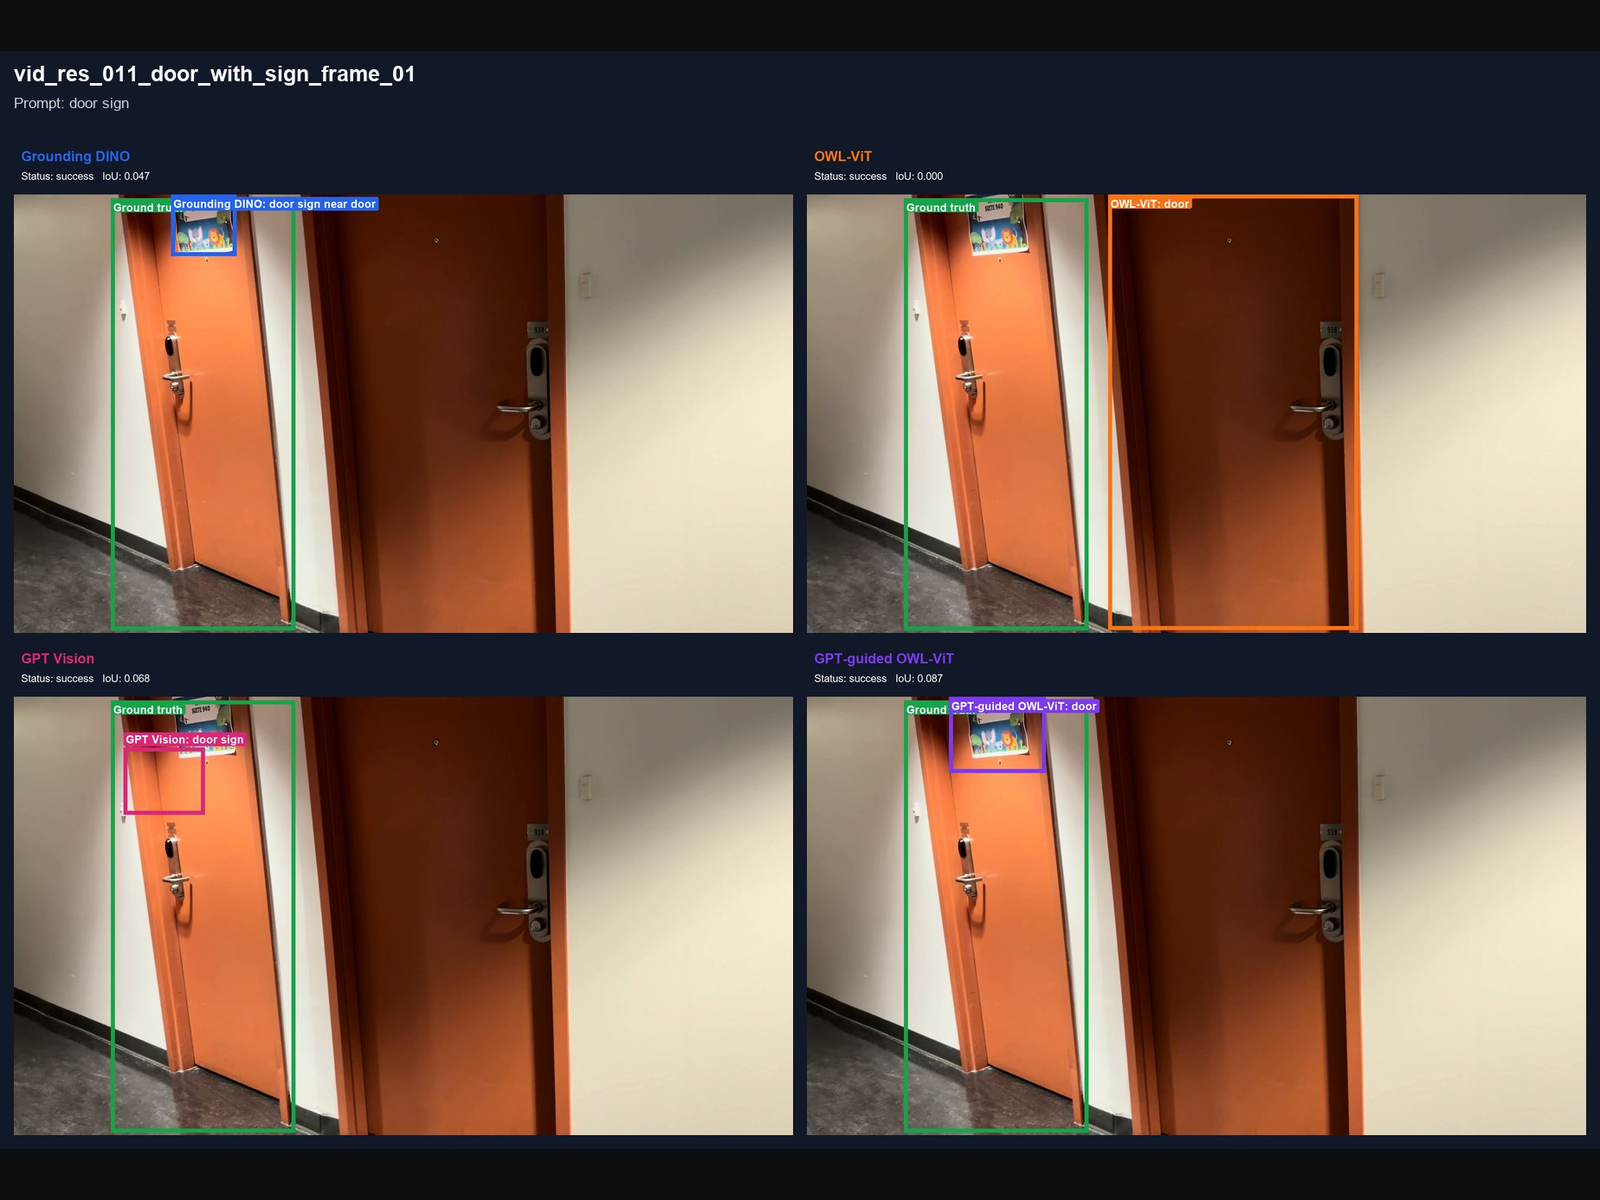
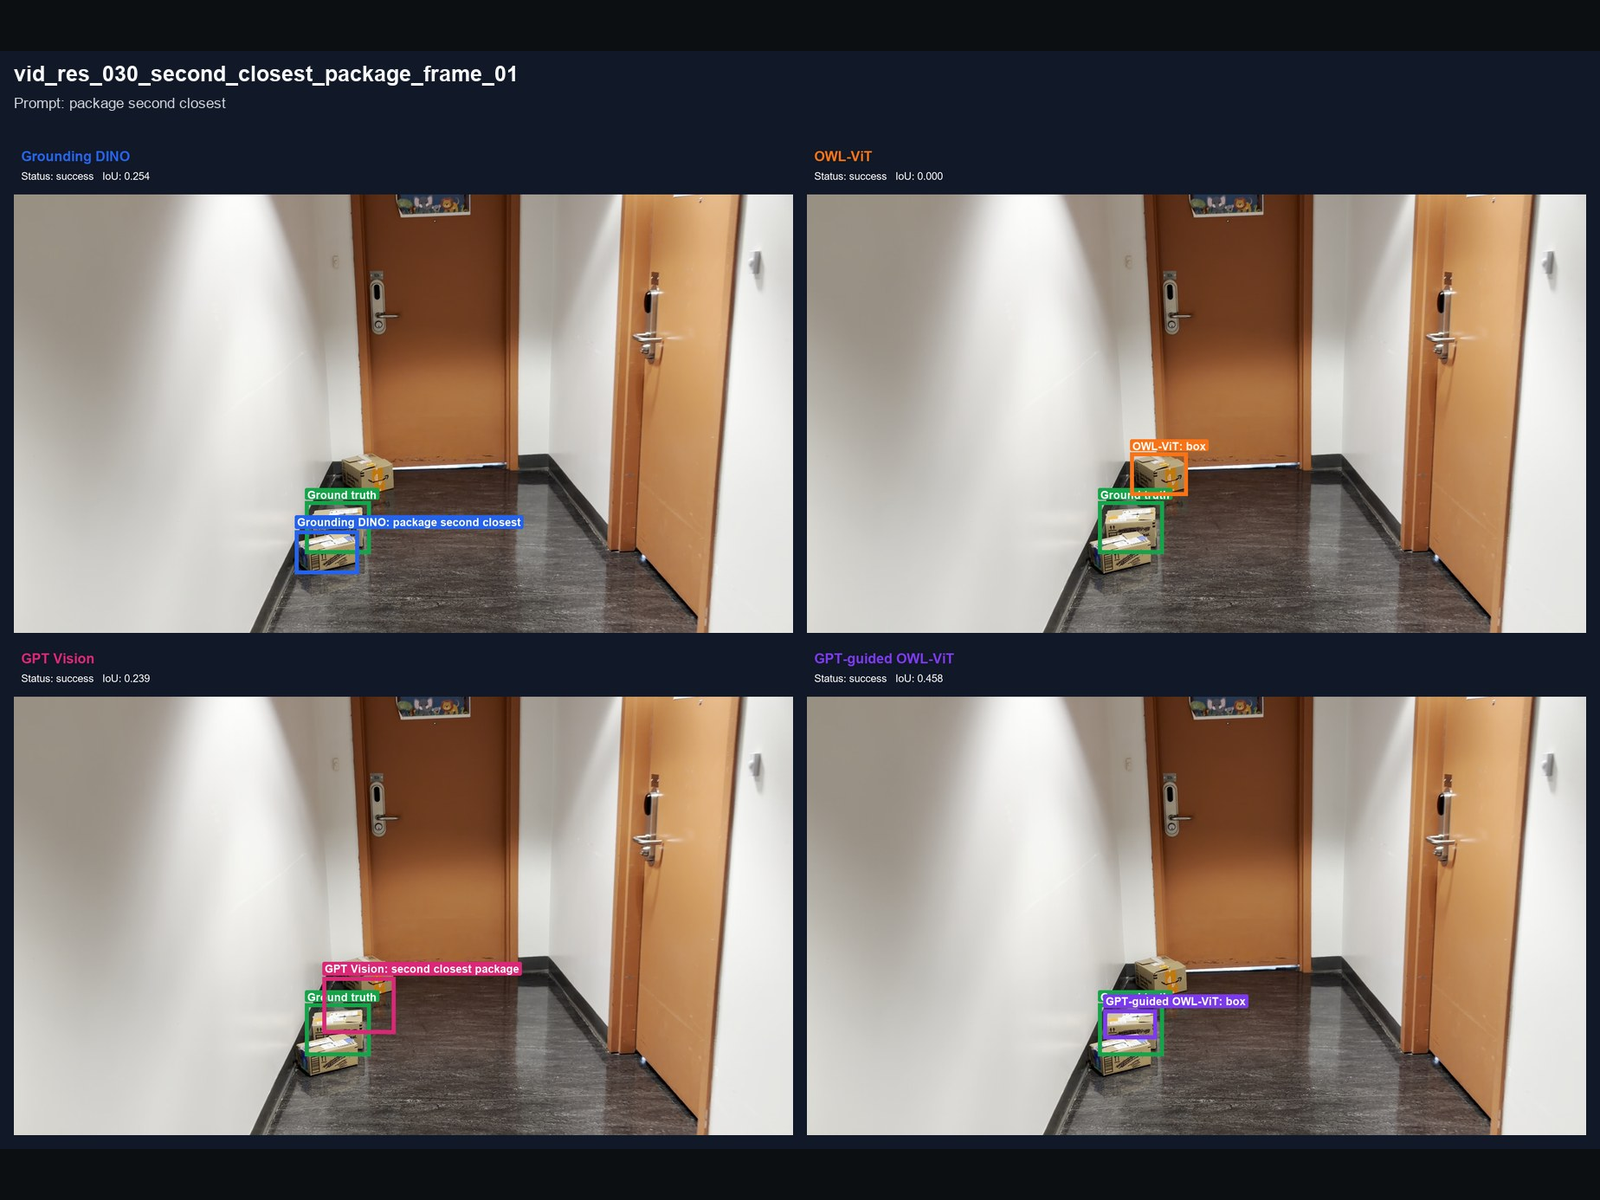
03
System overview
Request routing
- Natural-language instruction
- Parse objects · attributes · relations
- Route: YOLO / OWL-ViT / GPT-guided OWL-ViT
- Boxes · confidence · timing
04
Results
- 105
- Evaluation images
- 0.473
- Mean IoU
- 78.1%
- Success @ IoU ≥ 0.25
- 57.1%
- Success @ IoU ≥ 0.50
Results for the strongest configuration: the custom GPT Vision-guided OWL-ViT pipeline. The custom pipeline achieved the strongest mean IoU at 0.473, compared with OWL-ViT at 0.344, GPT Vision at 0.300 and Grounding DINO at 0.178 on the shared 105-image evaluation set.
05
Model comparison & custom pipeline
- 01Structure the natural-language task into targets, attributes, relations and anchors.
- 02Generate and rank open-vocabulary proposals with OWL-ViT.
- 03Use GPT Vision for instruction-aware candidate selection and ambiguity resolution.
- 04Refine locally and apply bounded box checks.
- 05Track and stabilize between model calls, recover from short losses and re-acquire when necessary.
06
Technology
- Python
- YOLO
- OWL-ViT
- GPT
- Browser camera
Next project
03 — ROS 2 Hardware Integration & Robotic Arm Bring-Up