
05Multimodal AI · Data Systems
Vision-Language Model Evaluation Pipeline
Built a reproducible evaluation pipeline for benchmarking vision-language models across standardized multimodal question-answering datasets.
- PySpark
- Parquet
- BLIP-2
- InstructBLIP
- LLaVA
01
What it does
Built a reproducible evaluation pipeline for benchmarking vision-language models across standardized multimodal question-answering datasets.
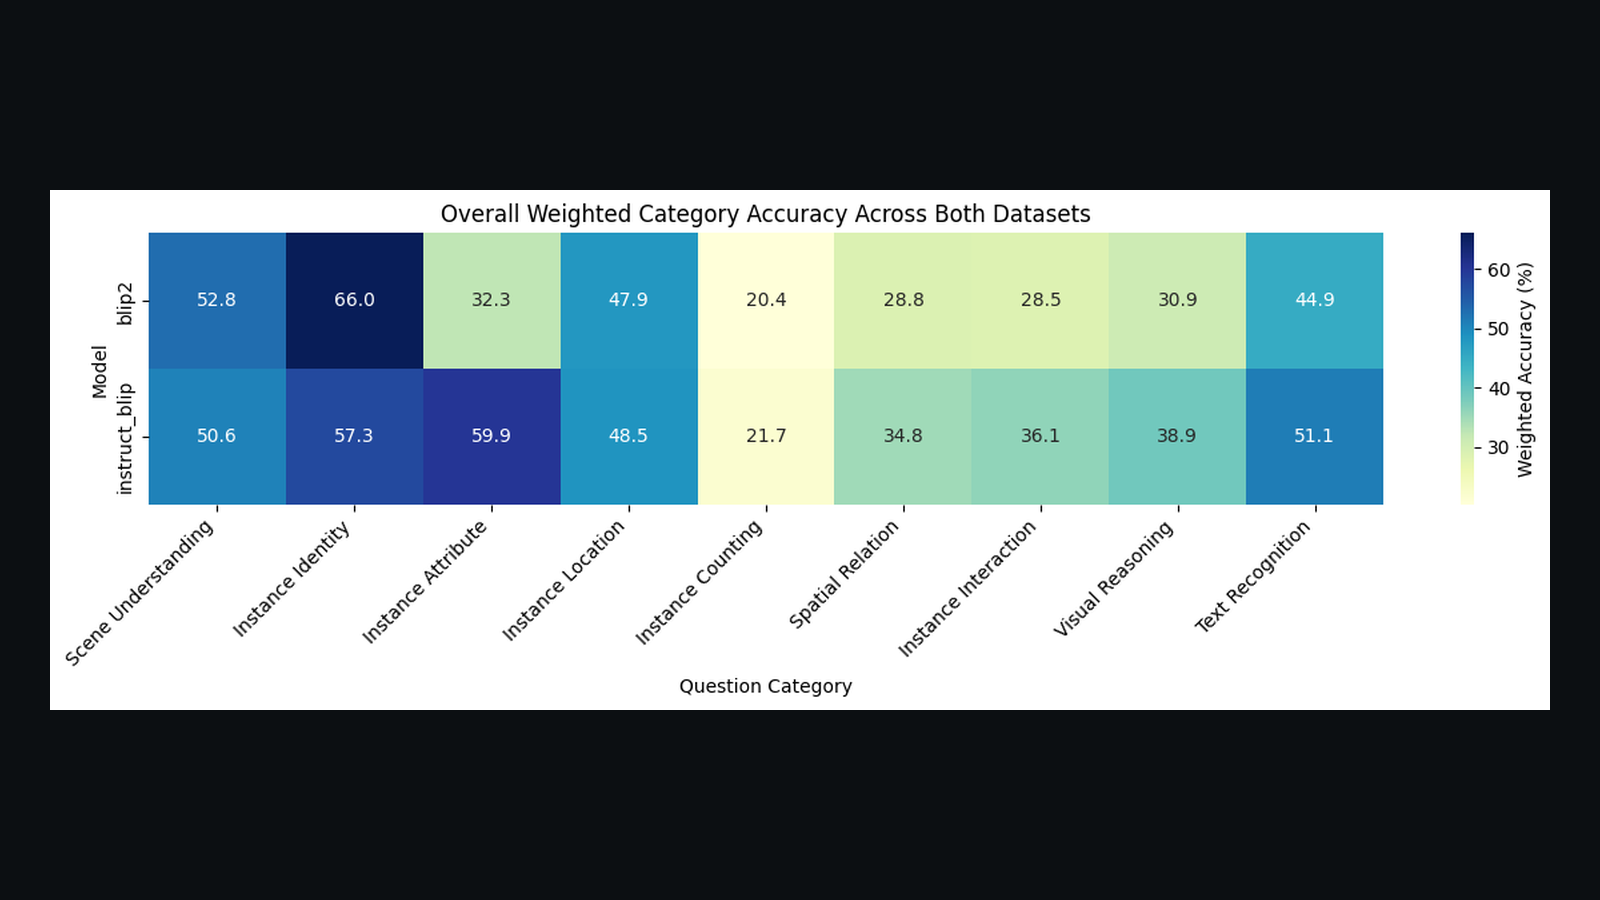
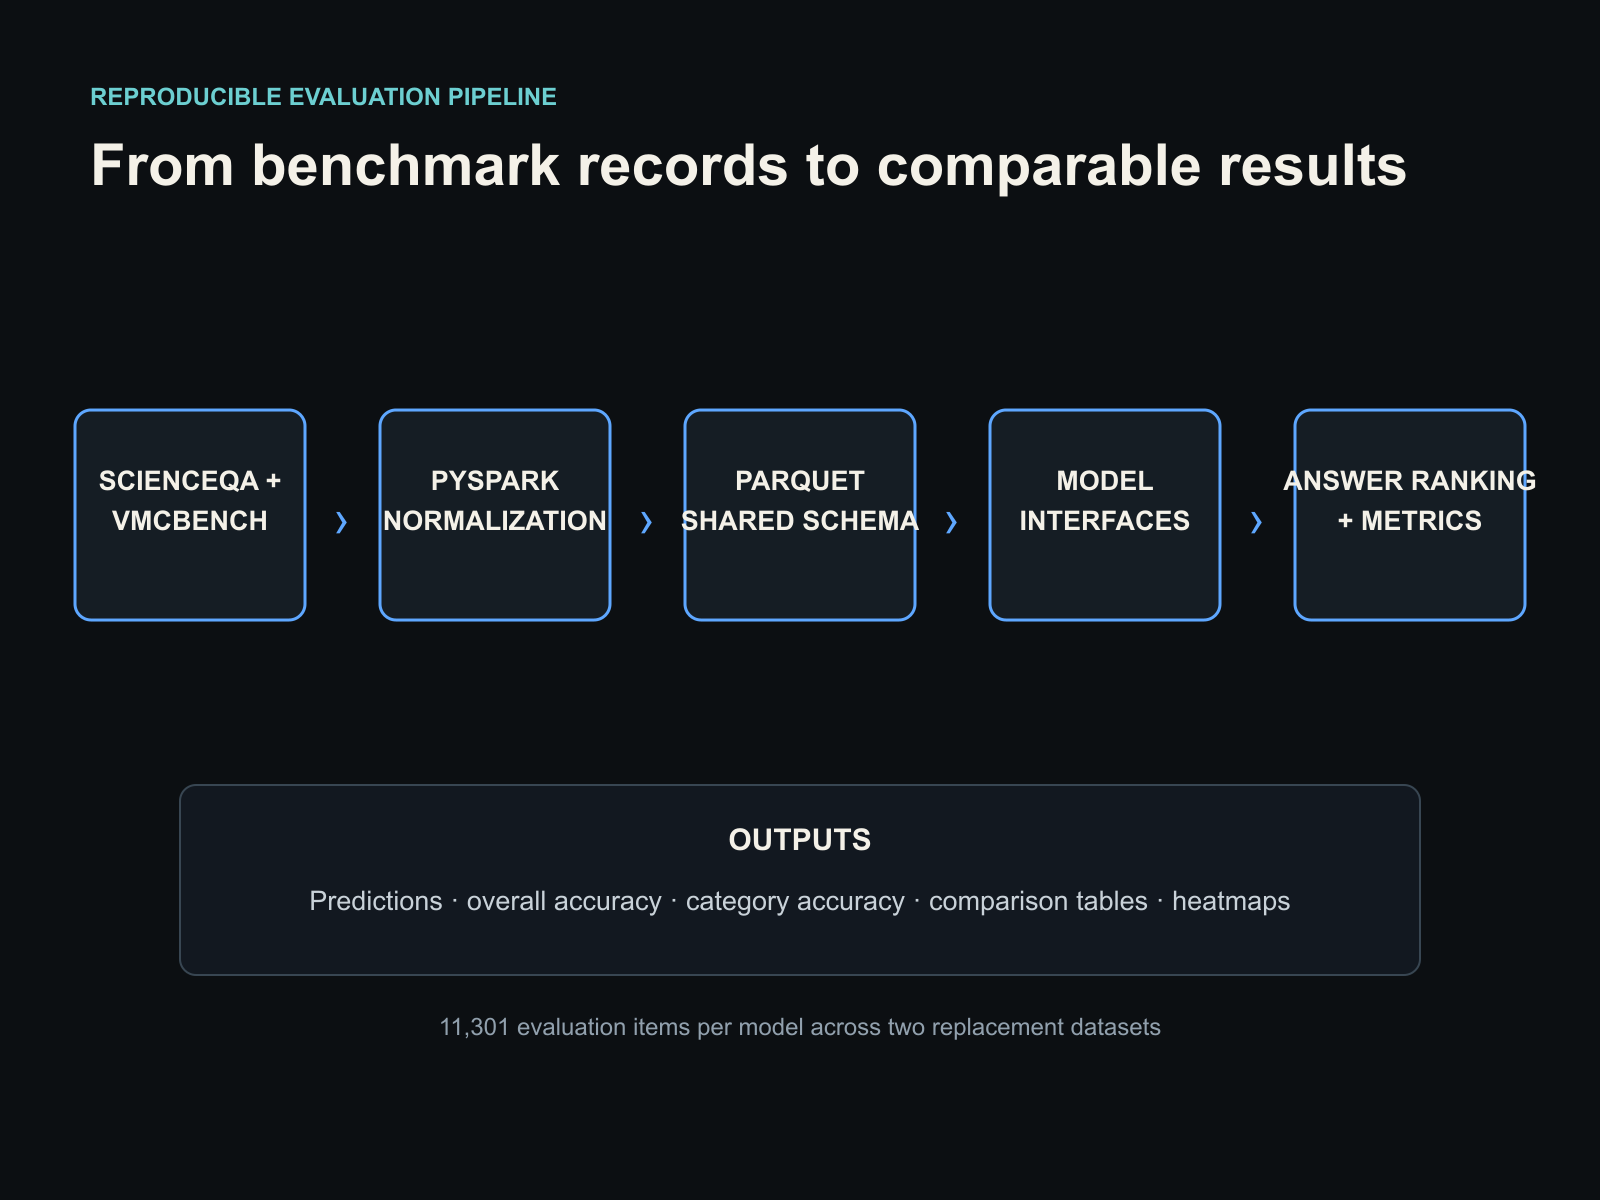
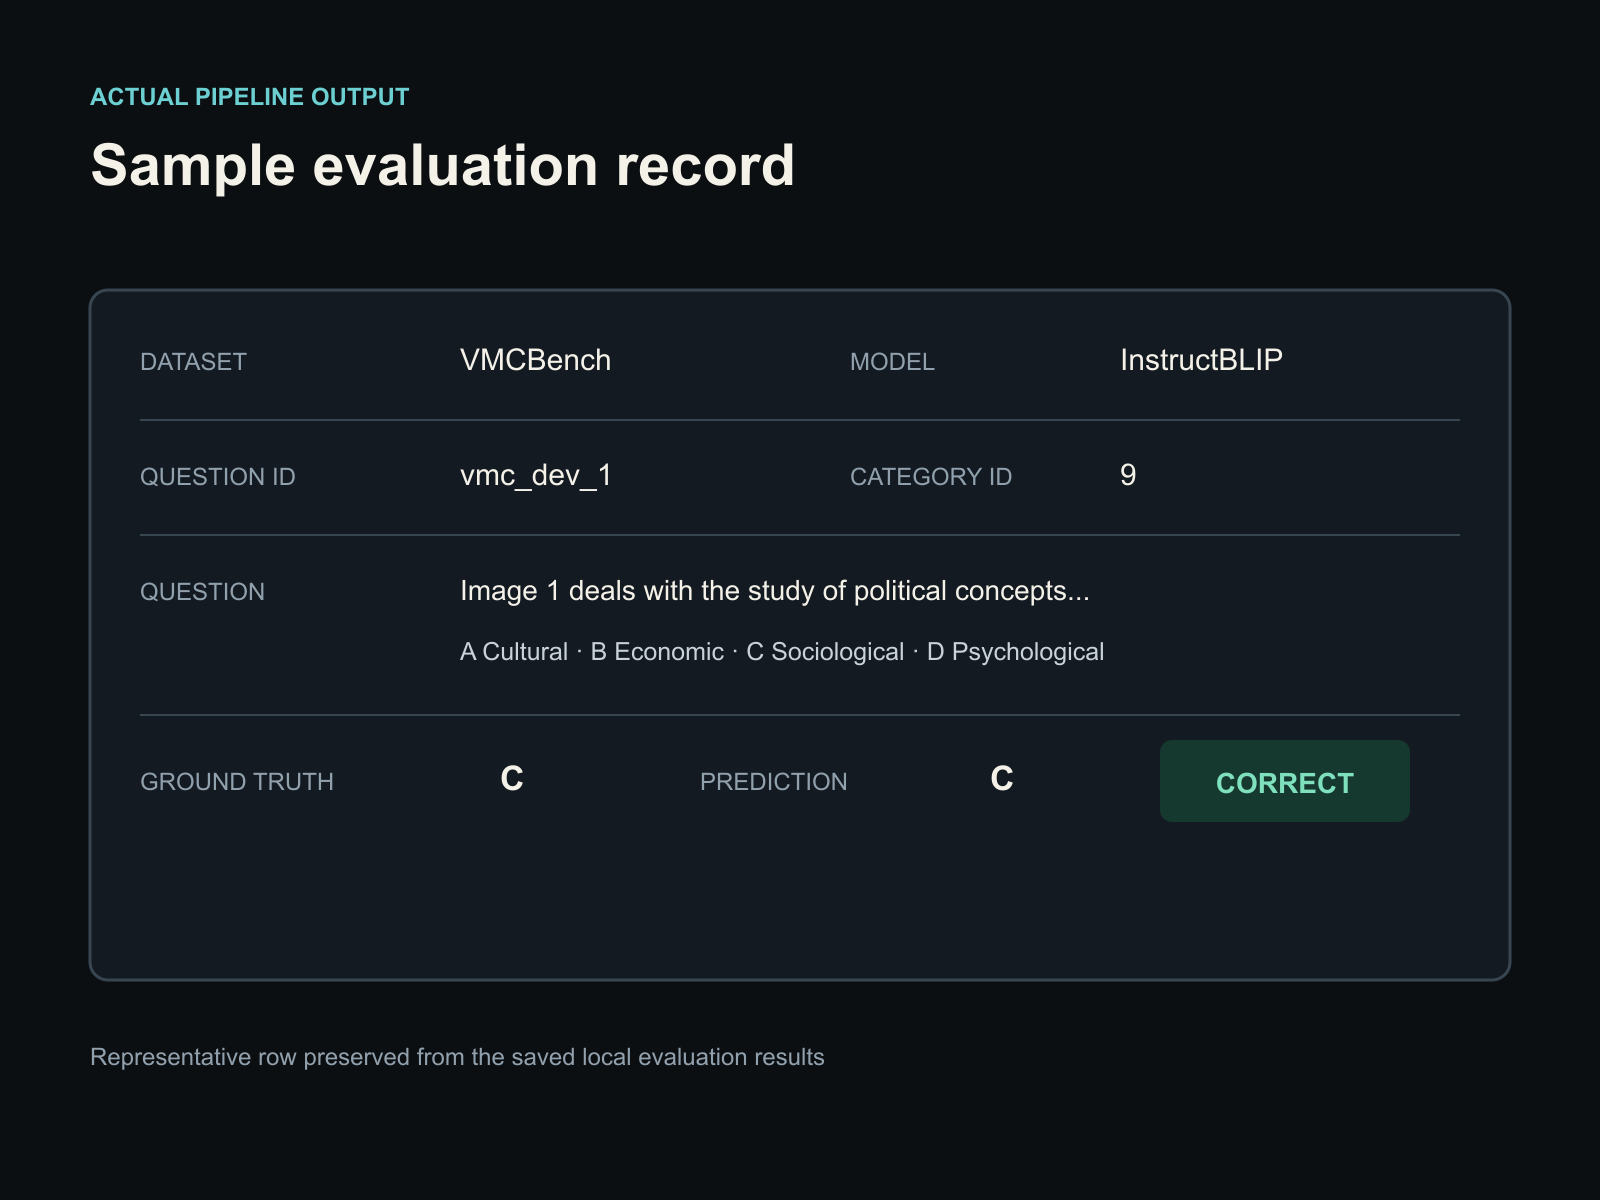
The system uses PySpark and Parquet to normalize benchmark records, provides model interfaces for BLIP-2, InstructBLIP and LLaVA-style workflows, performs answer-ranking evaluation and produces comparative results and heatmaps.
02
Demonstrations
03
Results
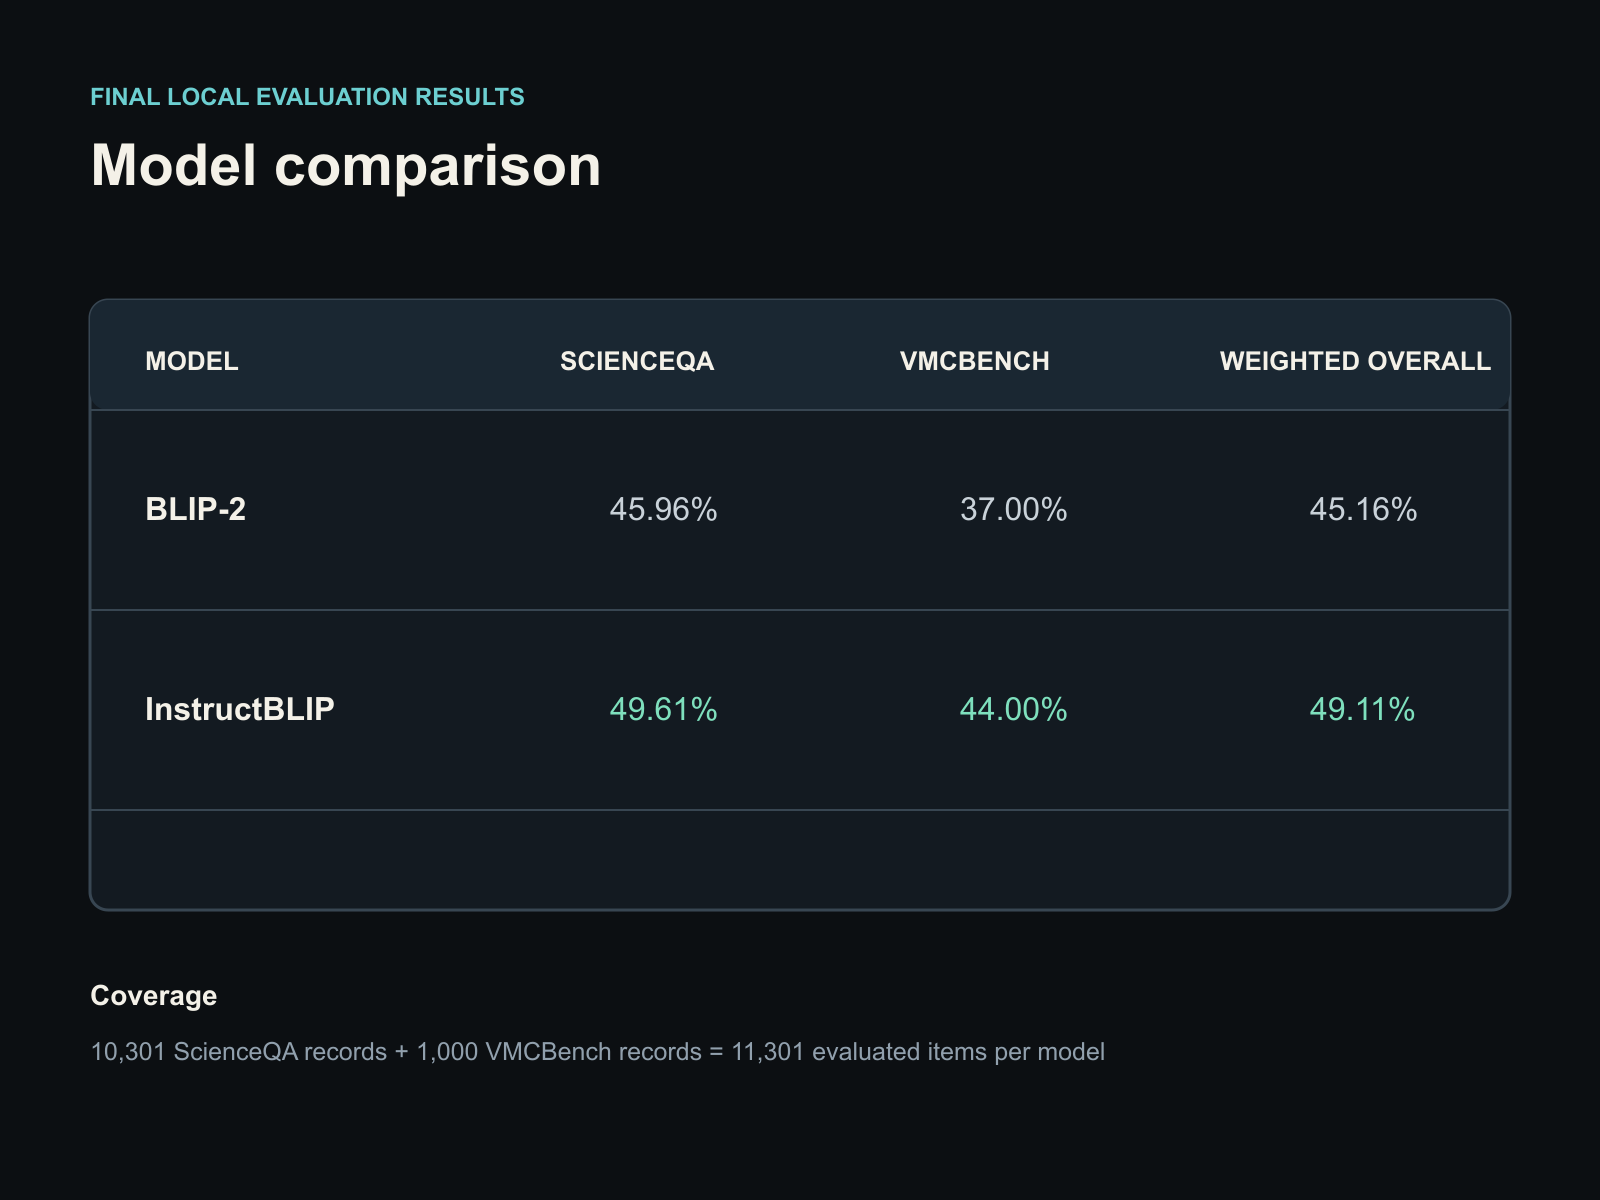
- 10,301
- ScienceQA records
- 1,000
- VMCBench records
- 11,301
- Evaluation items per model
- 49.11%
- InstructBLIP weighted accuracy
- 45.16%
- BLIP-2 weighted accuracy
04
Technology
- PySpark
- Parquet
- BLIP-2
- InstructBLIP
- LLaVA
- Python
Next project
01 — Physical AI Autonomous Delivery Robot